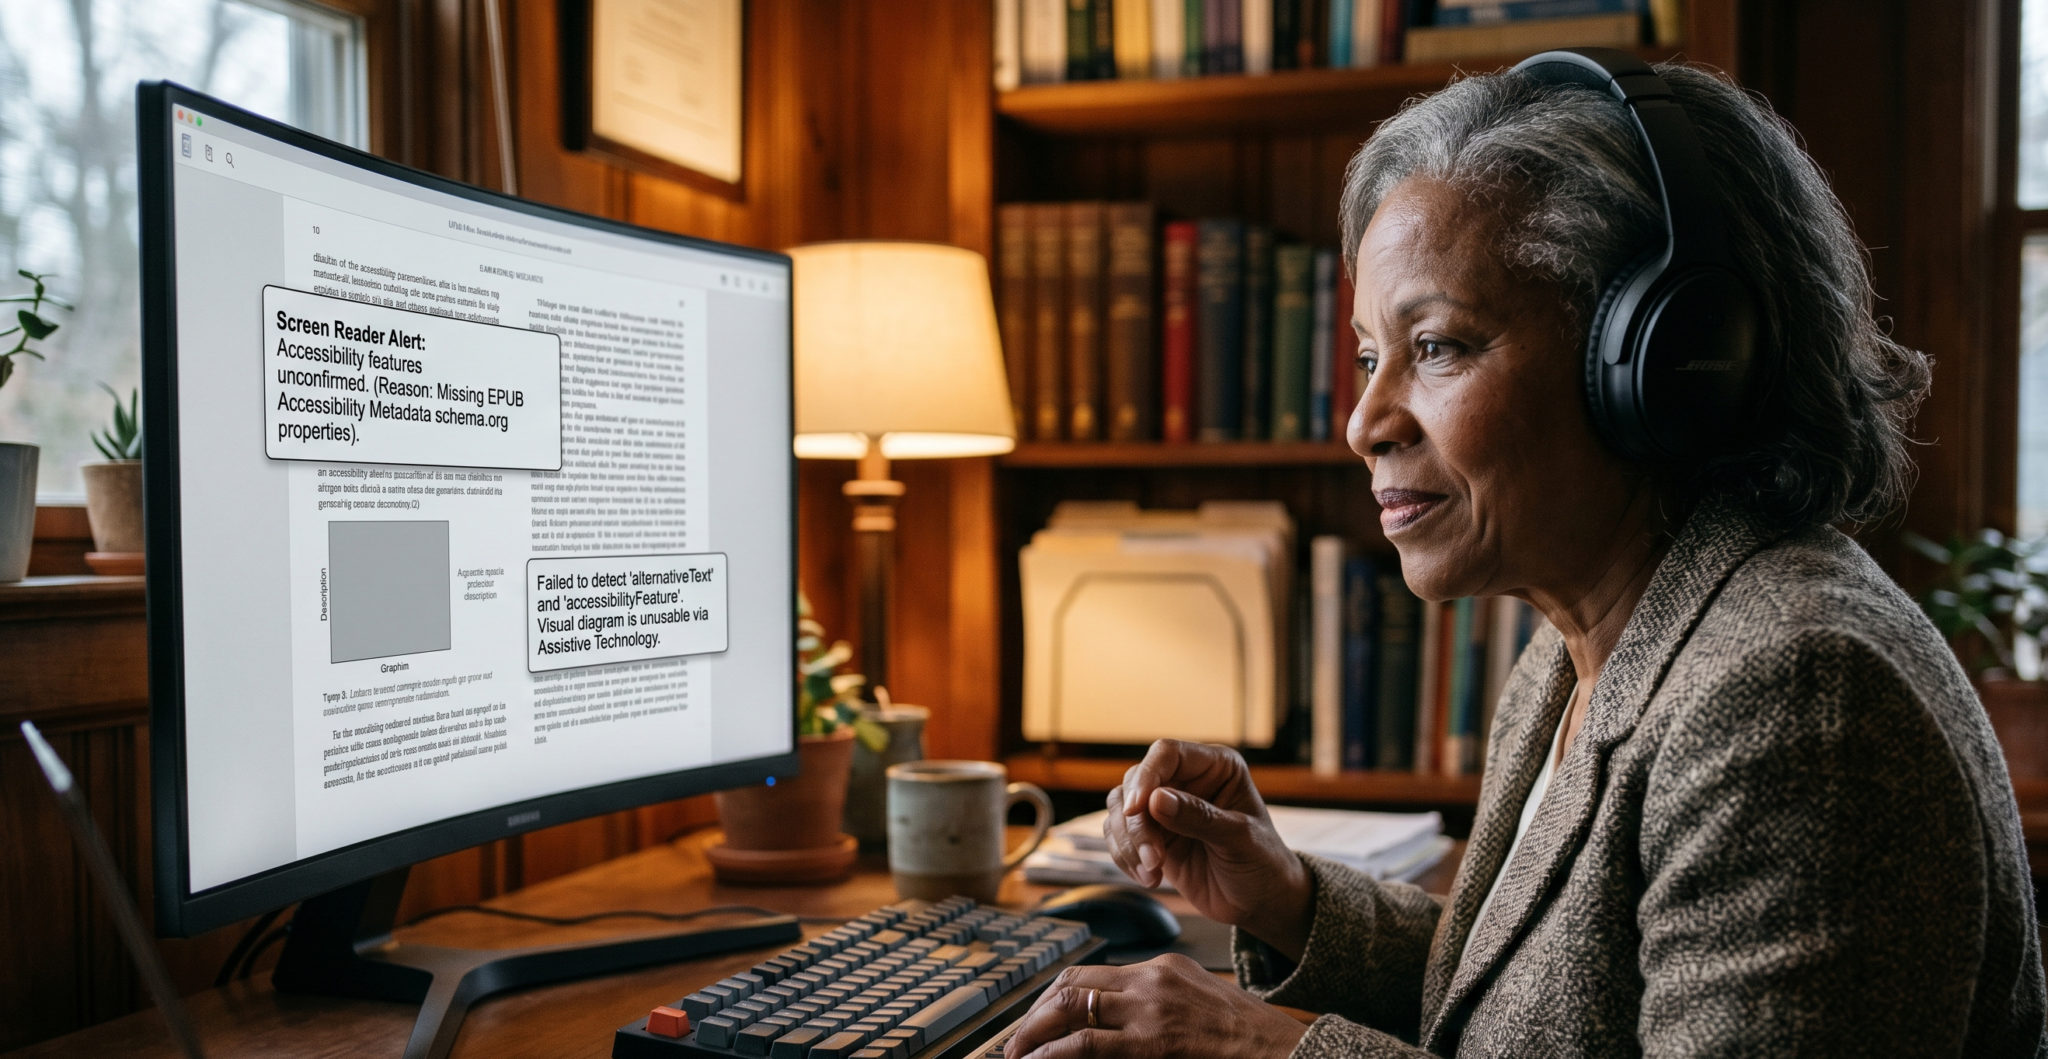
Accessibility metadata in EPUB is structured information, embedded using schema.org vocabulary and reflected in ONIX product records, that describes how accessible a digital publication actually is, covering things like navigation, alternative text, and reading order. Most EPUB files that pass WCAG 2.1 AA conformance checks still fail accessibility audits because the metadata describing that conformance is missing, incomplete, or never makes it into the file’s package.opf or the retailer’s ONIX feed.
Key Takeaways
- A file can be technically WCAG-conformant and still fail an accessibility audit if it lacks the schema.org accessibility metadata that declares this conformance.
- ONIX accessibility metadata (codelists 195, 196, and 197) is what retailers, libraries, and aggregators use to surface accessible titles to readers who need them.
- Without proper metadata, accessible EPUBs are effectively undiscoverable to users searching for accessible content, screen reader users, and procurement systems checking compliance.
- This is a high-impact, low-competition area: most accessibility content online focuses on the EPUB file itself, not the metadata layer that makes accessibility discoverable and auditable.
- BISG (Book Industry Study Group) maintains the primary guidance for implementing this metadata correctly across both EPUB and ONIX.
Why Does an Accessible EPUB Still Fail Compliance Audits?
An EPUB can pass every technical accessibility check, alt text present, reading order correct, navigation landmarks in place, and still fail a compliance audit for one reason: the file doesn’t say it’s accessible in a machine-readable way.
Compliance audits, particularly under the European Accessibility Act (EAA) and ADA Title II, increasingly check for two things, not one:
- Does the EPUB meet WCAG 2.1 AA requirements at the content and code level?
- Does the EPUB declare this conformance through standardized accessibility metadata that downstream systems, retailers, and libraries can read?
A file can satisfy the first condition entirely and fail the second. Auditors and procurement teams often rely on metadata fields to verify compliance at scale, rather than manually inspecting every file. If the metadata is absent, the file is frequently flagged as non-compliant by default, regardless of its actual internal accessibility.
What Is Schema.org Accessibility Metadata, and Where Does It Go in an EPUB?
- Funder mandates. Plan S (backed by cOAlition S, which includes many European national funders) requires that publications resulting from funded research be machine-readable and properly tagged with persistent identifiers, licensing metadata, and structured references.
- Repository requirements. PubMed Central, Europe PMC, and DOAJ all require JATS-conformant XML for full-text deposit. Without it, articles may be indexed with incomplete metadata or excluded entirely.
- Discoverability and citation tracking. Crossref’s citation-matching and reference-linking infrastructure depends on accurately tagged XML. Poorly structured XML leads to broken DOI links, missed citations, and lower visibility in scholarly search.
For journals based in the EU including the Netherlands, where Elsevier maintains its global headquarters and where open access policy is closely tied to national funder requirements this isn’t optional. It’s becoming the baseline expectation from funders, institutions, and readers alike.
What Does a Typical JATS XML Production Workflow Look Like
Schema.org accessibility metadata is a set of standardized properties, originally developed through a collaboration between the DAISY Consortium, the EPUB accessibility community, and schema.org, that describe the accessibility features of a digital publication in a way search engines, retailers, and assistive technologies can read.
| Schema.org Property | What It Describes | Example Value |
|---|---|---|
| accessibility Feature |
Specific accessibility features present | alternativeText, readingOrder, tableOfContents, MathML |
| accessibility Hazard |
Potential hazards for users with certain conditions | noFlashingHazard, noMotionSimulationHazard |
| accessibility Summary |
Human-readable summary of accessibility for the title | Free text description |
| accessibility API |
Accessibility APIs supported | ARIA |
| accessibility Control |
How the content can be controlled | fullKeyboardControl, fullMouseControl |
| conformsTo | Formal conformance standard | EPUB Accessibility 1.1, WCAG 2.1 Level AA |
In the EPUB file itself, this metadata belongs in the package.opf file, within the <metadata> element, using the schema: namespace. This is distinct from, but related to, the EPUB Accessibility 1.1 specification’s own conformance and certification metadata requirements.
The most commonly missing property in real-world EPUB files is accessibilitySummary. Even files with correctly tagged accessibilityFeature values frequently omit the human-readable summary, which is often the field retailers and library systems prioritize for display to end users.
How Does ONIX Accessibility Metadata Differ From EPUB Metadata?
JATS XML conversion timelines vary by article complexity, but for a standard 8,000–10,000 word STM research article with tables, figures, and 40–60 references, typical turnaround is:
- Simple articles (minimal tables/equations): 1–2 business days per article
- Moderate complexity (multiple tables, figures, supplementary files): 2–4 business days
- High complexity (heavy mathematical notation, large datasets, multimedia): 4–7 business days
Batch processing converting an entire issue or backlog at once typically reduces per-article turnaround by 20–30% due to shared style sheet setup and validation scripts across the batch.
How Long Does JATS XML Conversion Typically Take?
ONIX (ONline Information eXchange) is the metadata standard publishers use to communicate product information to retailers, distributors, and libraries, separately from the EPUB file itself. ONIX accessibility metadata carries the same underlying information as the schema.org properties inside the EPUB, but in a format retailers’ systems are built to ingest at the catalog level.
Key differences:
| Aspect | EPUB (Schema.org) Metadata | ONIX Metadata |
|---|---|---|
| Location | Embedded inside the EPUB file (package.opf) | Sent separately as part of the product record/feed |
| Primary Audience | Reading systems, assistive technology, the file itself | Retailers, distributors, library systems, aggregators |
| Used For | Determining how the content behaves for the reader | Determining how the title is displayed and filtered in a catalog |
| Relevant Codelists | N/A (uses schema.org vocabulary) | ONIX Codelist 196 (Accessibility feature), Codelist 195 (Accessibility hazard), and Codelist 197 (Accessibility API) |
| Common Failure Point | Missing accessibilitySummary | Accessibility fields present in EPUB but never mapped to the ONIX feed sent to retailers |
This is the gap that causes the most real-world compliance failures. A publisher may correctly tag the EPUB file but never update their ONIX feed to reflect it, meaning the title appears as “accessibility unknown” or “no information provided” on retailer platforms, libraries, and aggregator sites, even though the underlying file is fully accessible.
Why Does Accessibility Metadata Affect EPUB Discoverability?
EPUB discoverability for accessible titles depends almost entirely on metadata, not on the file’s actual internal accessibility, because discovery happens at the catalog level, before a reader ever opens the file.
Three discoverability impacts of missing or incomplete accessibility metadata:
- Library and institutional procurement systems filter by metadata. Many library systems, particularly those serving K-12 and academic institutions under ADA Title II obligations, allow filtering or flagging titles by accessibility conformance. A title without this metadata is often excluded from “accessible” results entirely, regardless of its actual conformance.
- Retailer accessibility labels depend on ONIX fields. Major retailers display accessibility information (such as “screen reader friendly” or accessibility feature badges) based on ONIX accessibility codelists. Without this data in the feed, no label appears, and the title is effectively invisible to readers specifically searching for accessible content.
- Search engines and AI-driven discovery tools increasingly surface accessibility information. As schema.org metadata is also used by search engines for structured data, properly tagged accessibility metadata can influence how a title appears in search results and AI-generated summaries, an emerging factor as generative search becomes more prevalent.
What Does a Complete Accessibility Metadata Checklist Look Like?
A complete accessibility metadata implementation, covering both the EPUB file and the ONIX feed, should include the following:
Inside the EPUB (package.opf):
- [ ] accessibilityFeature values listed for all applicable features (alt text, structural navigation, MathML, etc.)
- [ ] accessibilityHazard values declared, including “none” hazards explicitly (e.g., noFlashingHazard)
- [ ] accessibilitySummary written in clear, human-readable language
- [ ] accessibilityAPI declared (typically ARIA)
- [ ] accessibilityControl values present
- [ ] conformsTo referencing the correct standard (EPUB Accessibility 1.1, WCAG 2.1 AA)
In the ONIX feed:
- [ ] Codelist 196 (Accessibility feature) populated to match EPUB metadata
- [ ] Codelist 195 (Accessibility hazard) populated
- [ ] Codelist 197 (Accessibility API) populated
- [ ] Accessibility summary text included in the relevant ONIX text field
- [ ] Conformance certification details included where applicable (e.g., EPUB Accessibility 1.1 conformance statement)
Process checks:
- [ ] Metadata updated whenever the EPUB file itself is revised
- [ ] EPUB metadata and ONIX feed kept in sync as part of a single QC step, not handled separately
- [ ] Metadata validated against current BISG guidance, since codelists and recommended fields are periodically updated
How Can Publishers Fix This Without Re-Auditing Every Title?
Publishers with large backlists don’t need to re-run a full accessibility audit on every title to fix metadata gaps. A more efficient approach:
- Audit metadata first, separately from file-level accessibility. Many backlist titles may already meet WCAG requirements internally but simply lack declared metadata. A metadata-only audit is faster and often resolves the majority of “non-compliant” flags.
- Build a single metadata template per accessibility conformance level. Since most titles within a given production workflow share the same accessibility features (same navigation structure, same alt text practices), a standardized metadata block can often be applied across many titles with minimal per-title customization.
- Synchronize EPUB and ONIX updates in one pass. Treat the EPUB package.opf update and the ONIX feed update as a single task per title, rather than two separate projects, to avoid the most common failure point: EPUB updated, ONIX not.
- Validate against current BISG and EPUB Accessibility 1.1 guidance, as both the schema.org accessibility vocabulary and ONIX codelists have been revised in recent years, and older implementations may use deprecated field names or values.
Frequently Asked Questions
Is accessibility metadata legally required under the European Accessibility Act? The EAA requires that digital publications meet WCAG 2.1 AA conformance, and accessibility metadata is the primary mechanism by which this conformance is communicated and verified at scale. While the legal requirement centers on the content’s actual accessibility, metadata is increasingly treated as essential evidence of compliance during audits and procurement reviews.
Can a publisher add accessibility metadata without modifying the EPUB’s content or layout? Yes. Accessibility metadata is added to the package.opf file’s metadata section and does not require changes to the EPUB’s reading content, layout, or styling. It is a metadata-only update, which is one reason it is often overlooked, since it has no visible effect within the reading application itself.
What is the difference between EPUB Accessibility 1.0 and 1.1, and does it affect metadata? EPUB Accessibility 1.1 refined and clarified several metadata requirements compared to 1.0, including how conformance and certification are declared. Files tagged against the 1.0 specification may use older property structures that should be reviewed against current 1.1 guidance to ensure ongoing compatibility with audit tools.
How do retailers and libraries actually use ONIX accessibility codelists? Retailers and library systems ingest ONIX product feeds and use the accessibility codelist values, such as Codelist 196 for accessibility features, to populate filters, badges, and search facets. A title with no values in these fields typically appears with no accessibility information at all, rather than being assumed accessible or inaccessible.
How Wordium Can Help
Wordium’s accessibility services cover the full metadata layer, not just file-level remediation. This includes auditing existing EPUB files for schema.org accessibility metadata completeness, reviewing and updating ONIX accessibility feeds to match, and building standardized metadata templates for backlist titles to avoid re-auditing every file individually.
If your accessible titles aren’t appearing as accessible to retailers, libraries, or procurement systems, the issue is often metadata, not the file itself. Contact Wordium’s accessibility team for a metadata audit.
Related Wordium Services: Accessibility (WCAG/EPUB) | eBook Creation (EPUB3) | Digital Conversion (XML, HTML, PDF)
Frequently Asked Questions
What is an XML-first publishing workflow?
An XML-first publishing workflow is a production model in which XML is created at the earliest stage of the editorial process during copyediting or composition and used as the single canonical source from which all output formats (PDF, EPUB3, HTML, print) are generated. This contrasts with XML-last workflows, where XML is produced as a final export from formatted files. XML-first workflows improve consistency across formats, reduce per-format correction cycles, and enable automated multi-format output from a single validated source.
Which XML schema should STM journals use, JATS or BITS?
STM journal articles should use JATS (Journal Article Tag Suite), which is the standard required by PubMed Central, CrossRef, Scopus, and most major academic aggregators. BITS (Book Interchange Tag Suite) is the appropriate schema for academic books and monographs it is structurally compatible with JATS but extends it to support book-level structural elements such as chapters, front matter, and back matter.
How does metadata affect journal discoverability on aggregator platforms?
Aggregator platforms including PubMed, Scopus, Web of Science, and ProQuest index content based on structured metadata fields. Missing or incorrectly coded subject classifications, incomplete author affiliation records, or unregistered DOIs can result in articles being excluded from relevant search results, incorrectly categorized within subject areas, or absent from citation indexes entirely. Metadata errors are frequently invisible to the editorial team but have a direct and measurable impact on article reach and citation rates.
What should I look for in the best digital conversion services in the US?
The best digital conversion services in the US go beyond file format transformation to deliver schema-validated, accessibility-compliant, metadata-complete output that passes platform ingestion requirements without remediation. Key indicators include: XML-first production capability, support for JATS, BITS, and ONIX standards, EPUB3 output that meets EPUB Accessibility 1.1 requirements, multi-format generation from a single XML source, and demonstrated experience with STM, academic, or K–12 publisher workflows.
How do I convert a manuscript to EPUB3 without losing formatting?
Reliable manuscript-to-EPUB3 conversion requires a structured XML intermediary not direct conversion from Word or PDF. The process involves: creating or validating a JATS or BITS XML source, applying semantic tagging for headings, figures, tables, footnotes, and equations, and then generating EPUB3 from that validated XML source. Direct conversion from unstructured formats produces EPUB files with inconsistent rendering across devices and frequent accessibility failures.
What is the difference between ONIX and Dublin Core metadata?
ONIX (Online Information eXchange) is a detailed commercial metadata standard used to communicate bibliographic, pricing, rights, and availability information between publishers, distributors, and retail platforms. It is the standard required by Amazon, Apple Books, Kobo, and most library platform providers. Dublin Core is a simpler, more general metadata standard used primarily for web resource description and archival purposes. Dublin Core has fifteen core elements and is used in open access repositories and library catalog systems; ONIX 3.0 has hundreds of codelist elements designed to support complex commercial publishing data requirements.
Can one XML source file produce PDF, HTML, and EPUB outputs?
Yes and for high-volume publishers, this is the primary operational argument for XML-first workflows. A single validated XML source file, properly structured against JATS or BITS schema, can serve as the input for automated transformation pipelines that generate print-ready PDF, web-delivery HTML, and EPUB3 simultaneously. Any content correction made to the XML source propagates to all output formats, eliminating version drift and reducing per-format quality assurance effort significantly.