A JATS XML workflow converts journal manuscripts into Journal Article Tag Suite (JATS) format the NLM/NISO standard used by PubMed Central, DOAJ, Crossref, and most major repositories. For open access (OA) publishers, a structured JATS workflow is what makes articles discoverable, indexable, and compliant with funder mandates like Plan S, all while reducing production turnaround time by 30–50% compared to manual tagging.
Key Takeaways
- JATS XML is the de facto global standard for structuring journal article content for archiving, indexing, and distribution.
- Open access mandates (Plan S, Horizon Europe, NIH Public Access Policy) increasingly require XML-first or XML-parallel output, not just PDF.
- A well-built JATS workflow reduces time-to-publication, minimizes manual rework, and improves metadata accuracy for discovery platforms.
- Publishers across the EU including those based in the Netherlands, home to Elsevier's global headquarters are under growing pressure to standardize XML output across multi-journal portfolios.
- Outsourcing JATS conversion to specialists with JATS, DTD validation, and editorial QC expertise is now standard practice for mid-to-large STM publishers.
Why Are Open Access Journals Moving to XML-First Production?
Open access journals are moving to XML-first production because repositories, aggregators, and funder compliance systems are built to ingest structured XML not PDF. PDF remains the human-readable “version of record” for most readers, but it is not machine-actionable. XML is.
Three forces are driving this shift:
A publishing platform is the technical and distribution environment through which content is delivered, hosted, and discovered by readers. The wrong platform choice doesn’t just limit reach, it creates structural incompatibilities with your XML workflows and metadata standards that generate compounding inefficiencies across every production cycle.
- Funder mandates. Plan S (backed by cOAlition S, which includes many European national funders) requires that publications resulting from funded research be machine-readable and properly tagged with persistent identifiers, licensing metadata, and structured references.
- Repository requirements. PubMed Central, Europe PMC, and DOAJ all require JATS-conformant XML for full-text deposit. Without it, articles may be indexed with incomplete metadata or excluded entirely.
- Discoverability and citation tracking. Crossref’s citation-matching and reference-linking infrastructure depends on accurately tagged XML. Poorly structured XML leads to broken DOI links, missed citations, and lower visibility in scholarly search.
For journals based in the EU including the Netherlands, where Elsevier maintains its global headquarters and where open access policy is closely tied to national funder requirements this isn’t optional. It’s becoming the baseline expectation from funders, institutions, and readers alike.
What Does a Typical JATS XML Production Workflow Look Like
A typical JATS XML workflow for an open access journal follows six stages, moving from manuscript intake to final repository deposit.
| Stage | What Happens | Common Output |
|---|---|---|
| 1. Manuscript Intake | Author manuscript received in Word, LaTeX, or PDF; structural elements identified. | Cleaned source file |
| 2. Copyediting & Pre-editing | Language editing, reference formatting, and terminology consistency checks. | Edited manuscript |
| 3. XML Tagging & Conversion | Content converted to JATS-compliant XML (Archiving, Publishing, or Authoring DTD). | Validated JATS XML file |
| 4. Typesetting & Composition | Parallel PDF and HTML generation from or alongside the XML. | Print-ready PDF, HTML |
| 5. QC & Validation | DTD/schema validation, reference linking checks, and accessibility verification. | QC report, corrected XML |
| 6. Repository Deposit | XML and metadata pushed to PubMed Central, Crossref, DOAJ, and institutional repositories. | Indexed, discoverable article |
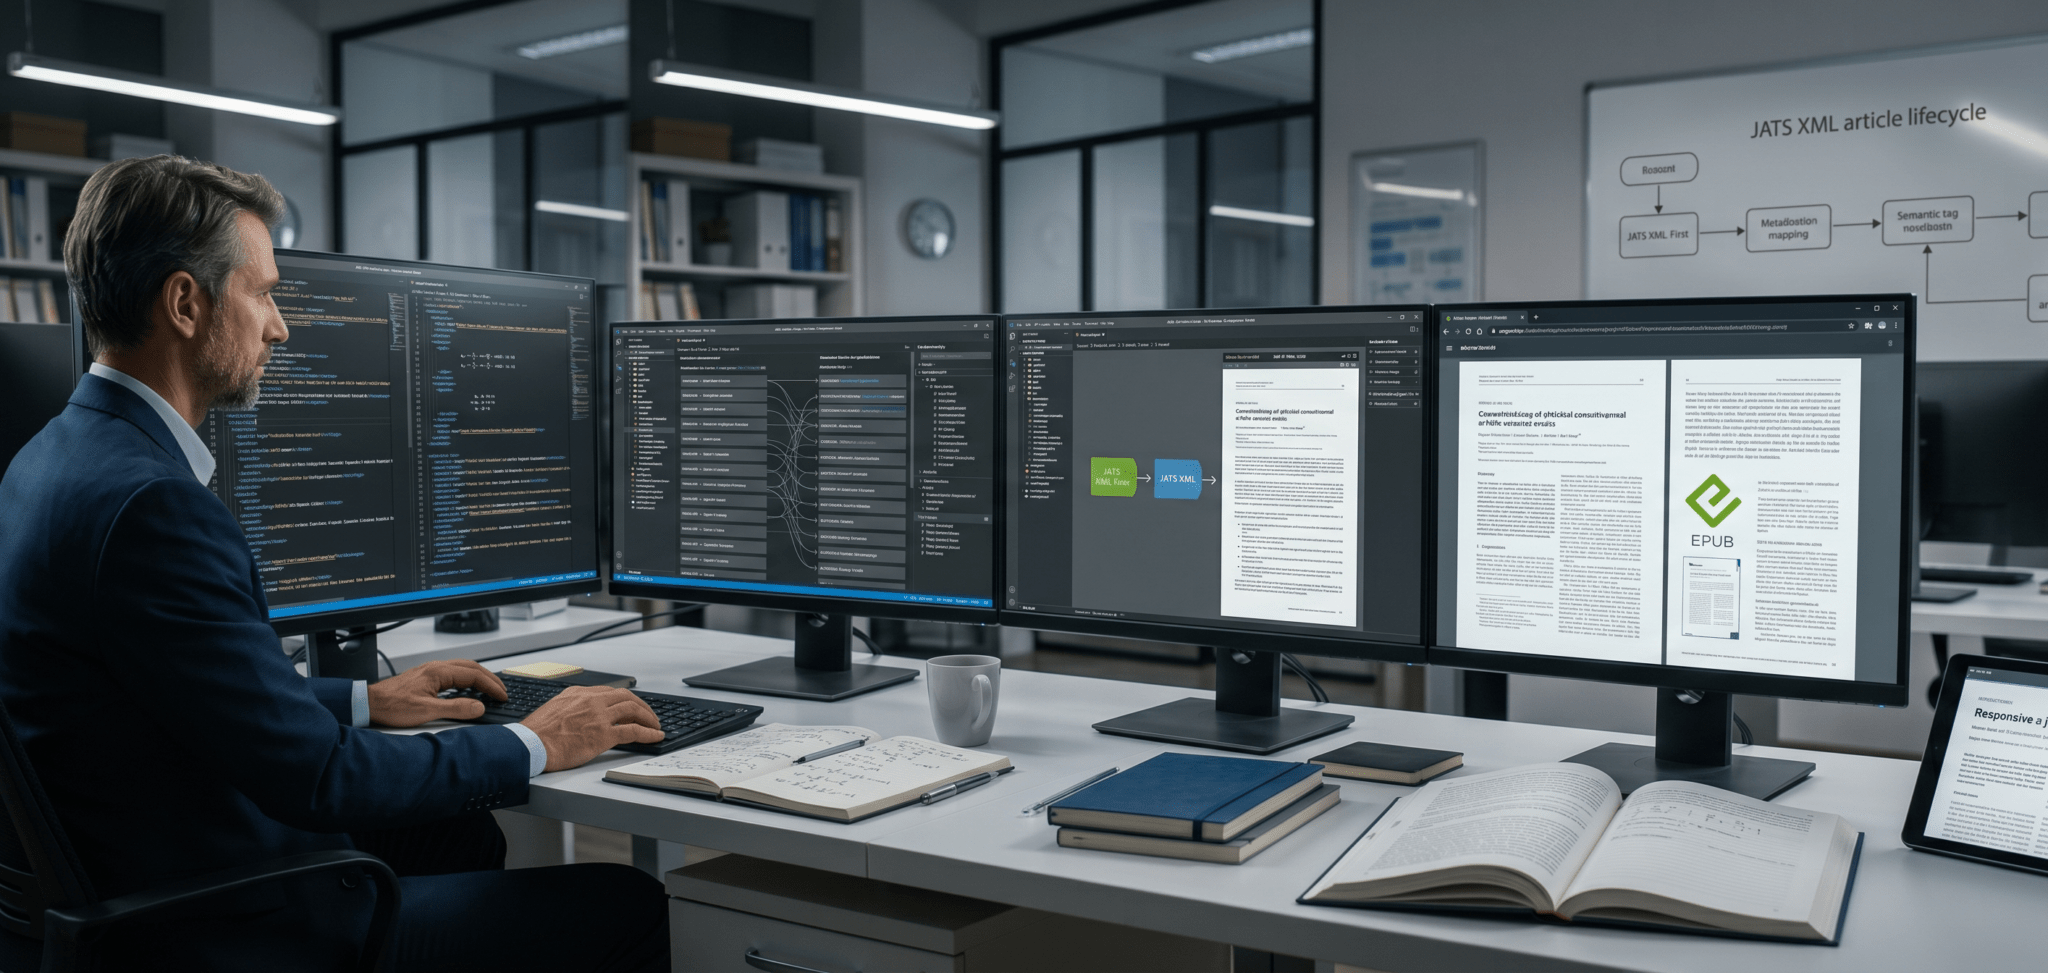
The most efficient workflows run steps 3 and 4 in parallel generating XML, PDF, and HTML from a single structured source rather than treating XML as an afterthought derived from a finished PDF. This “XML-first” approach is what allows publishers to hit faster turnaround times without sacrificing accuracy.
Which JATS DTD Should an Open Access Journal Use?
The right JATS DTD depends on where the XML will be deposited and how it will be reused.
- JATS Archiving and Interchange DTD the most comprehensive tag set, required by PubMed Central and most repositories for long-term archiving. This is the default choice for most OA journals.
- JATS Publishing DTD a streamlined subset used by some publishers for their own production systems before converting to the Archiving DTD for deposit.
- JATS Authoring DTD designed for use earlier in the workflow, when authors or editors are tagging content before full production.
For most open access STM journals, the Archiving and Interchange DTD is the safest default, since it’s the version PubMed Central, Europe PMC, and most aggregators expect on ingest.
How Long Does JATS XML Conversion Typically Take?
JATS XML conversion timelines vary by article complexity, but for a standard 8,000–10,000 word STM research article with tables, figures, and 40–60 references, typical turnaround is:
- Simple articles (minimal tables/equations): 1–2 business days per article
- Moderate complexity (multiple tables, figures, supplementary files): 2–4 business days
- High complexity (heavy mathematical notation, large datasets, multimedia): 4–7 business days
Batch processing converting an entire issue or backlog at once typically reduces per-article turnaround by 20–30% due to shared style sheet setup and validation scripts across the batch.
What Are the Most Common JATS XML Errors That Delay Publication?
The most common errors that cause JATS XML to fail validation or repository ingest are:
- Incorrect or missing DOI and ORCID tagging leads to broken links in Crossref and author disambiguation failures.
- Malformed reference lists inconsistent citation styles converted incorrectly, breaking citation-matching.
- Improper table and equation encoding tables converted as images instead of structured XML tables; equations not encoded in MathML.
- Missing or incomplete metadata funder information, licensing (CC BY, CC BY-NC, etc.), and article history dates omitted or incorrectly tagged.
- DTD validation failures XML that doesn’t conform to the declared schema, often caught only at the repository deposit stage, causing rejection and rework.
Catching these errors before deposit through automated DTD validation combined with manual editorial QC prevents costly rejection cycles with repositories, which can delay publication by days or weeks.
Wordium vs. In-House XML Production: A Quick Comparison
| Factor | In-House Production | Outsourced JATS Workflow (Wordium) |
|---|---|---|
| Setup Time | Weeks to months (hiring, training, tooling) | Immediate existing trained teams |
| Cost | Higher (salaries, software licenses, infrastructure) | 40–60% lower than Western in-house costs |
| Scalability for backlog/issue spikes | Limited by headcount | Flexible capacity for batch and peak loads |
| JATS/DTD expertise | Requires ongoing training as standards evolve | Specialist teams working across multiple DTD versions daily |
| QC and validation | Often manual, inconsistent | Automated DTD validation + AI-assisted QC + manual editorial review |
| Parallel output (XML + PDF + HTML) | Often sequential, slower | Built into XML-first workflow |
How Can Open Access Publishers Prepare for Stricter XML Requirements?
Publishers can prepare for tightening XML and accessibility requirements by taking four practical steps:
- Audit current XML output against the latest JATS version your target repositories require, since DTD versions are periodically updated.
- Standardize metadata capture at submission funder IDs, ORCID, and licensing information should be collected structurally at manuscript submission, not reconstructed later.
- Move to XML-first or XML-parallel production rather than converting from finished PDFs, which is slower and more error-prone.
- Pair XML conversion with accessibility compliance since EPUB and HTML outputs derived from JATS XML must also meet WCAG 2.1 AA standards under the European Accessibility Act for any EU-distributed digital content.
This last point matters particularly for publishers operating in or distributing into the EU, including the Netherlands, where accessibility compliance and open access XML requirements now overlap a journal’s XML isn’t just for indexing anymore, it’s also the source for accessible digital formats.
Frequently Asked Questions
What is the difference between JATS and NLM DTD? JATS (Journal Article Tag Suite) is the NISO-standardized successor to the earlier NLM DTD. JATS is now the actively maintained standard, while NLM DTD versions are considered legacy. Most repositories now require JATS-conformant XML, though many systems still accept NLM-tagged files for backward compatibility during transition periods.
Do all open access journals need JATS XML, or only those depositing in PubMed Central? While PubMed Central explicitly requires JATS XML for deposit, other repositories and aggregators including Europe PMC, Crossref, and many institutional repositories also expect JATS-conformant XML for full functionality, including accurate citation linking and metadata harvesting. Journals that only produce PDF risk reduced discoverability even outside PubMed Central.
Can JATS XML be generated automatically without manual tagging? Partial automation is possible using AI-assisted conversion tools, particularly for well-structured manuscripts with consistent formatting. However, manual editorial QC remains essential for reference accuracy, table/equation encoding, and metadata validation fully automated conversion without review carries a high risk of validation failures at deposit.
How does JATS XML relate to EPUB and accessibility compliance? JATS XML can serve as the structured source from which EPUB files are generated, since both formats rely on tagged, semantic content rather than visual layout. When JATS XML is properly tagged including alt text for figures, table headers, and reading order the resulting EPUB is better positioned to meet WCAG 2.1 AA requirements under regulations like the European Accessibility Act.
How Wordium Can Help
Wordium provides end-to-end JATS XML conversion for open access journals from manuscript intake and copyediting through DTD validation, parallel XML/PDF/HTML production, and repository-ready deposit packages. Our teams work across JATS Archiving, Publishing, and Authoring DTDs, with AI-assisted QC layered on top of manual editorial review to catch the errors that cause repository rejections before they happen.
If your journal’s XML workflow is creating bottlenecks or if you’re preparing for stricter funder and accessibility requirements get in touch with Wordium’s XML production team to discuss a workflow audit.
Related Wordium Services: XML Conversion | Copyediting & Indexing | Accessibility (WCAG/EPUB) | Typesetting & Composition
Frequently Asked Questions
What is an XML-first publishing workflow?
An XML-first publishing workflow is a production model in which XML is created at the earliest stage of the editorial process during copyediting or composition and used as the single canonical source from which all output formats (PDF, EPUB3, HTML, print) are generated. This contrasts with XML-last workflows, where XML is produced as a final export from formatted files. XML-first workflows improve consistency across formats, reduce per-format correction cycles, and enable automated multi-format output from a single validated source.
Which XML schema should STM journals use, JATS or BITS?
STM journal articles should use JATS (Journal Article Tag Suite), which is the standard required by PubMed Central, CrossRef, Scopus, and most major academic aggregators. BITS (Book Interchange Tag Suite) is the appropriate schema for academic books and monographs it is structurally compatible with JATS but extends it to support book-level structural elements such as chapters, front matter, and back matter.
How does metadata affect journal discoverability on aggregator platforms?
Aggregator platforms including PubMed, Scopus, Web of Science, and ProQuest index content based on structured metadata fields. Missing or incorrectly coded subject classifications, incomplete author affiliation records, or unregistered DOIs can result in articles being excluded from relevant search results, incorrectly categorized within subject areas, or absent from citation indexes entirely. Metadata errors are frequently invisible to the editorial team but have a direct and measurable impact on article reach and citation rates.
What should I look for in the best digital conversion services in the US?
The best digital conversion services in the US go beyond file format transformation to deliver schema-validated, accessibility-compliant, metadata-complete output that passes platform ingestion requirements without remediation. Key indicators include: XML-first production capability, support for JATS, BITS, and ONIX standards, EPUB3 output that meets EPUB Accessibility 1.1 requirements, multi-format generation from a single XML source, and demonstrated experience with STM, academic, or K–12 publisher workflows.
How do I convert a manuscript to EPUB3 without losing formatting?
Reliable manuscript-to-EPUB3 conversion requires a structured XML intermediary not direct conversion from Word or PDF. The process involves: creating or validating a JATS or BITS XML source, applying semantic tagging for headings, figures, tables, footnotes, and equations, and then generating EPUB3 from that validated XML source. Direct conversion from unstructured formats produces EPUB files with inconsistent rendering across devices and frequent accessibility failures.
What is the difference between ONIX and Dublin Core metadata?
ONIX (Online Information eXchange) is a detailed commercial metadata standard used to communicate bibliographic, pricing, rights, and availability information between publishers, distributors, and retail platforms. It is the standard required by Amazon, Apple Books, Kobo, and most library platform providers. Dublin Core is a simpler, more general metadata standard used primarily for web resource description and archival purposes. Dublin Core has fifteen core elements and is used in open access repositories and library catalog systems; ONIX 3.0 has hundreds of codelist elements designed to support complex commercial publishing data requirements.
Can one XML source file produce PDF, HTML, and EPUB outputs?
Yes and for high-volume publishers, this is the primary operational argument for XML-first workflows. A single validated XML source file, properly structured against JATS or BITS schema, can serve as the input for automated transformation pipelines that generate print-ready PDF, web-delivery HTML, and EPUB3 simultaneously. Any content correction made to the XML source propagates to all output formats, eliminating version drift and reducing per-format quality assurance effort significantly.