Key Takeaways
- Platform selection is a workflow decision, not just a technology preference; the wrong platform creates structural debt that compounds with every new title.
- XML-first workflows reduce production costs and error rates at scale; XML-last approaches are a relic that most high-volume publishers are actively retiring.
- Metadata isn't descriptive decoration, it is operational infrastructure. Errors in ONIX, DOI registration, or Dublin Core directly suppress discoverability and revenue.
- A single validated XML source file can generate PDF, EPUB3, HTML, and print-ready output eliminating redundant production passes and inconsistency between formats.
- Accessibility (WCAG, ADA, EPUB Accessibility) is now a legal and commercial prerequisite, not an optional enhancement and it must be designed into the workflow, not retrofitted.
Your content is editorial gold. Your peer review is rigorous. Your authors are credible. And yet your journal articles are underperforming on aggregator platforms, your eBook conversions are inconsistent across retailers, and your production team is manually re-keying metadata into three separate systems. The content isn’t the problem. The infrastructure is.
For publishers operating at scale whether managing thousands of STM journal articles per quarter, running K–12 curriculum pipelines, or bringing academic monographs to global trade markets the gap between well-produced content and successful, discoverable publication almost always comes down to three interconnected systems: publishing platforms, XML workflows, and metadata. Understanding how these three layers interact is the operational insight that separates publishers who grow from those who stagnate.
What Are Publishing Platforms and Why Choosing the Wrong One Costs You More Than You Think
A publishing platform is the technical and distribution environment through which content is delivered, hosted, and discovered by readers. The wrong platform choice doesn’t just limit reach, it creates structural incompatibilities with your XML workflows and metadata standards that generate compounding inefficiencies across every production cycle.
Publishing platforms fall into three broad categories, each serving distinct distribution and workflow functions.
Journal hosting platforms such as OJS (Open Journal Systems), Highwire Press, and Silverchair are purpose-built for STM and academic publishers managing peer-reviewed content. They handle manuscript submission, editorial workflow, article-level metadata, DOI assignment, and reader access in an integrated environment. Platform selection here directly influences how your JATS XML is ingested, how CrossRef metadata is registered, and whether your content surfaces correctly in PubMed, Scopus, or Web of Science.
Trade and consumer retail platforms Kindle Direct Publishing, Apple Books, Kobo Writing Life, and Google Play Books serve fiction, non-fiction, and educational publishers targeting retail audiences. These platforms ingest EPUB3 files and ONIX metadata feeds. Errors in either frequently result in incorrect retail listings, missing pricing data, and suppressed search rankings within platform ecosystems.
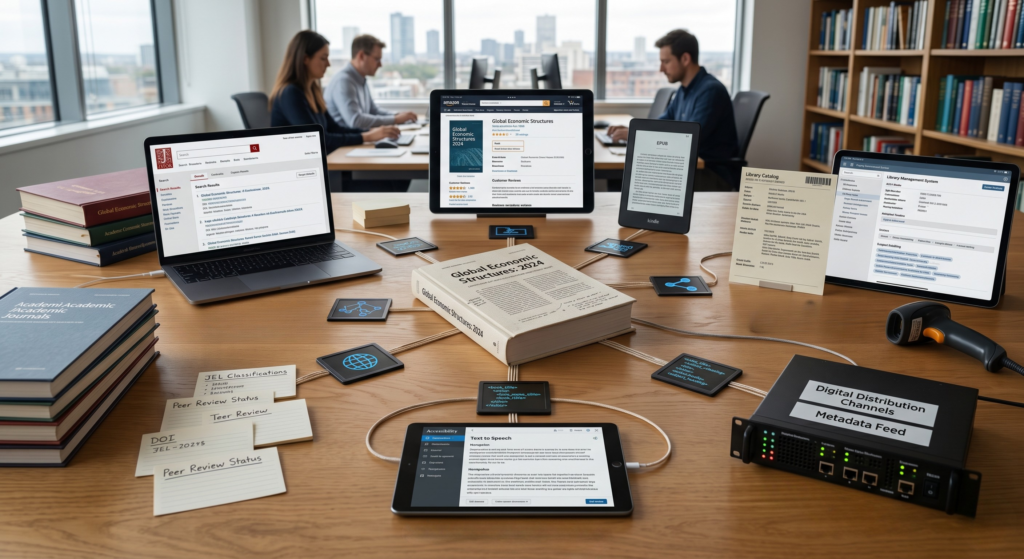
Academic aggregators and library platforms JSTOR, ProQuest, EBSCO, and Muse act as secondary distribution layers for institutional access. Their metadata requirements often differ from primary journal platforms, meaning publishers must maintain multiple metadata streams simultaneously.
Hosted vs. Self-Managed Platforms What's the Real Tradeoff?
Hosted platforms (Silverchair, Atypon) absorb infrastructure management but introduce dependency on the vendor’s XML ingestion pipeline and upgrade cycle. Self-managed instances (OJS) offer flexibility but require internal technical capacity to maintain schema compatibility and system updates. The decision should be evaluated not in isolation but against your existing XML workflow maturity: a fully XML-first production environment can feed almost any platform efficiently; a fragmented, format-first workflow will struggle regardless of which platform you choose.
XML Workflows Explained The Engine Behind Scalable Publishing
An XML workflow is a structured, schema-validated production process in which content is authored, edited, and transformed using XML as the canonical format from which all output formats (PDF, EPUB3, HTML, print) are generated. The distinction between XML-first and XML-last workflows is the single most consequential architectural decision in modern publishing operations.
In an XML-first workflow, XML is created at the earliest possible stage often during copyediting or composition and all subsequent outputs are derived from that validated source. In an XML-last (or “convert-at-end”) workflow, content is produced in word processors or InDesign, and XML is generated as a final export, typically for archiving or aggregator submission. The difference in operational impact is significant.
XML-last workflows produce inconsistent output because the XML is derived from a formatted document rather than a structured source, and any structural irregularities in the formatted file carry through into the XML. XML-first workflows invert this relationship: structure is enforced upstream, and formatting is applied downstream from validated content, producing consistent multi-format output with fewer manual correction cycles.
DTD and Schema Standards: JATS, BITS, ONIX, DocBook When to Use Which
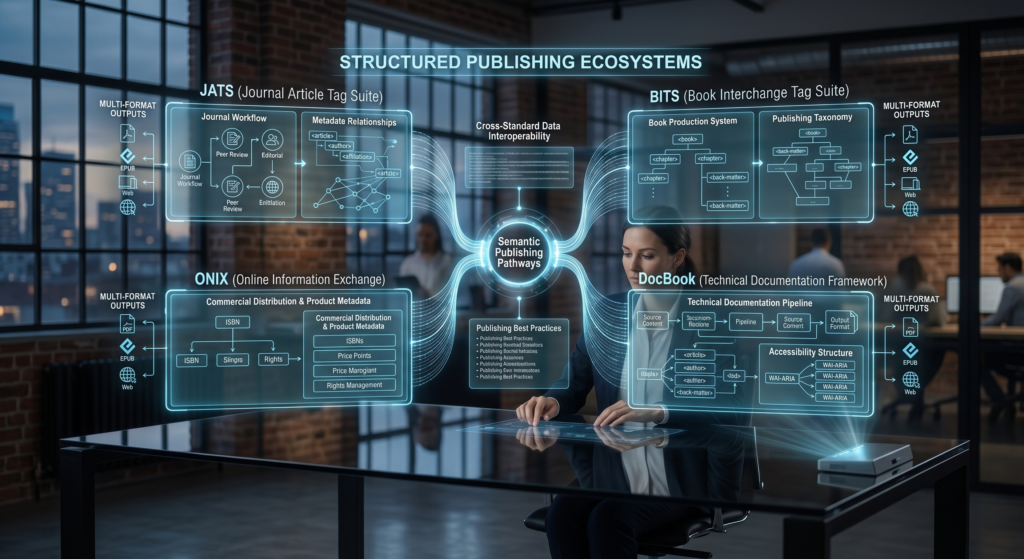
Schema selection is determined by content type and distribution target, not preference.
- JATS (Journal Article Tag Suite) is the standard schema for peer-reviewed journal articles. It is required by most major aggregators and archiving bodies (PubMed Central, CrossRef, Portico) and supports article-level semantic tagging for citations, figures, tables, and supplementary data.
- BITS (Book Interchange Tag Suite) is the JATS-compatible standard for academic books and monographs, enabling chapter-level metadata and structured front matter.
- ONIX (Online Information eXchange) is a metadata standard not a content schema used to communicate bibliographic and commercial data between publishers, distributors, and retailers. ONIX 3.0 is the current version required by most major retail platforms.
- DocBook is used primarily for technical documentation and manuals, with strong support for versioning and modular content reuse, common in software and engineering publishing contexts.
How XML-First Workflows Reduce Production Costs and Error
Publishers working with XML-first workflows consistently report material reductions in format-specific correction rounds. When EPUB3, PDF, and HTML are all generated from a single validated XML source, any content correction is made once and propagates across all formats eliminating the version drift that occurs when each format is managed as a separate file. For high-volume STM publishers processing thousands of articles per quarter, this architectural difference compounds into substantial labor savings.
Common XML Workflow Mistakes Publishers Make (and How to Fix Them)
The most frequent mistake is treating XML as a downstream export rather than an upstream source resulting in structurally invalid XML that requires extensive manual remediation before it can be ingested by aggregators or converted to EPUB. The second most common error is schema inconsistency: applying JATS markup conventions inconsistently across issues or volumes, which breaks automated processing pipelines. Both are fundamentally workflow design problems, not technology problems, and both are resolved by establishing schema validation checkpoints earlier in the production cycle.
Metadata for Publishing The Invisible Infrastructure of Discoverability
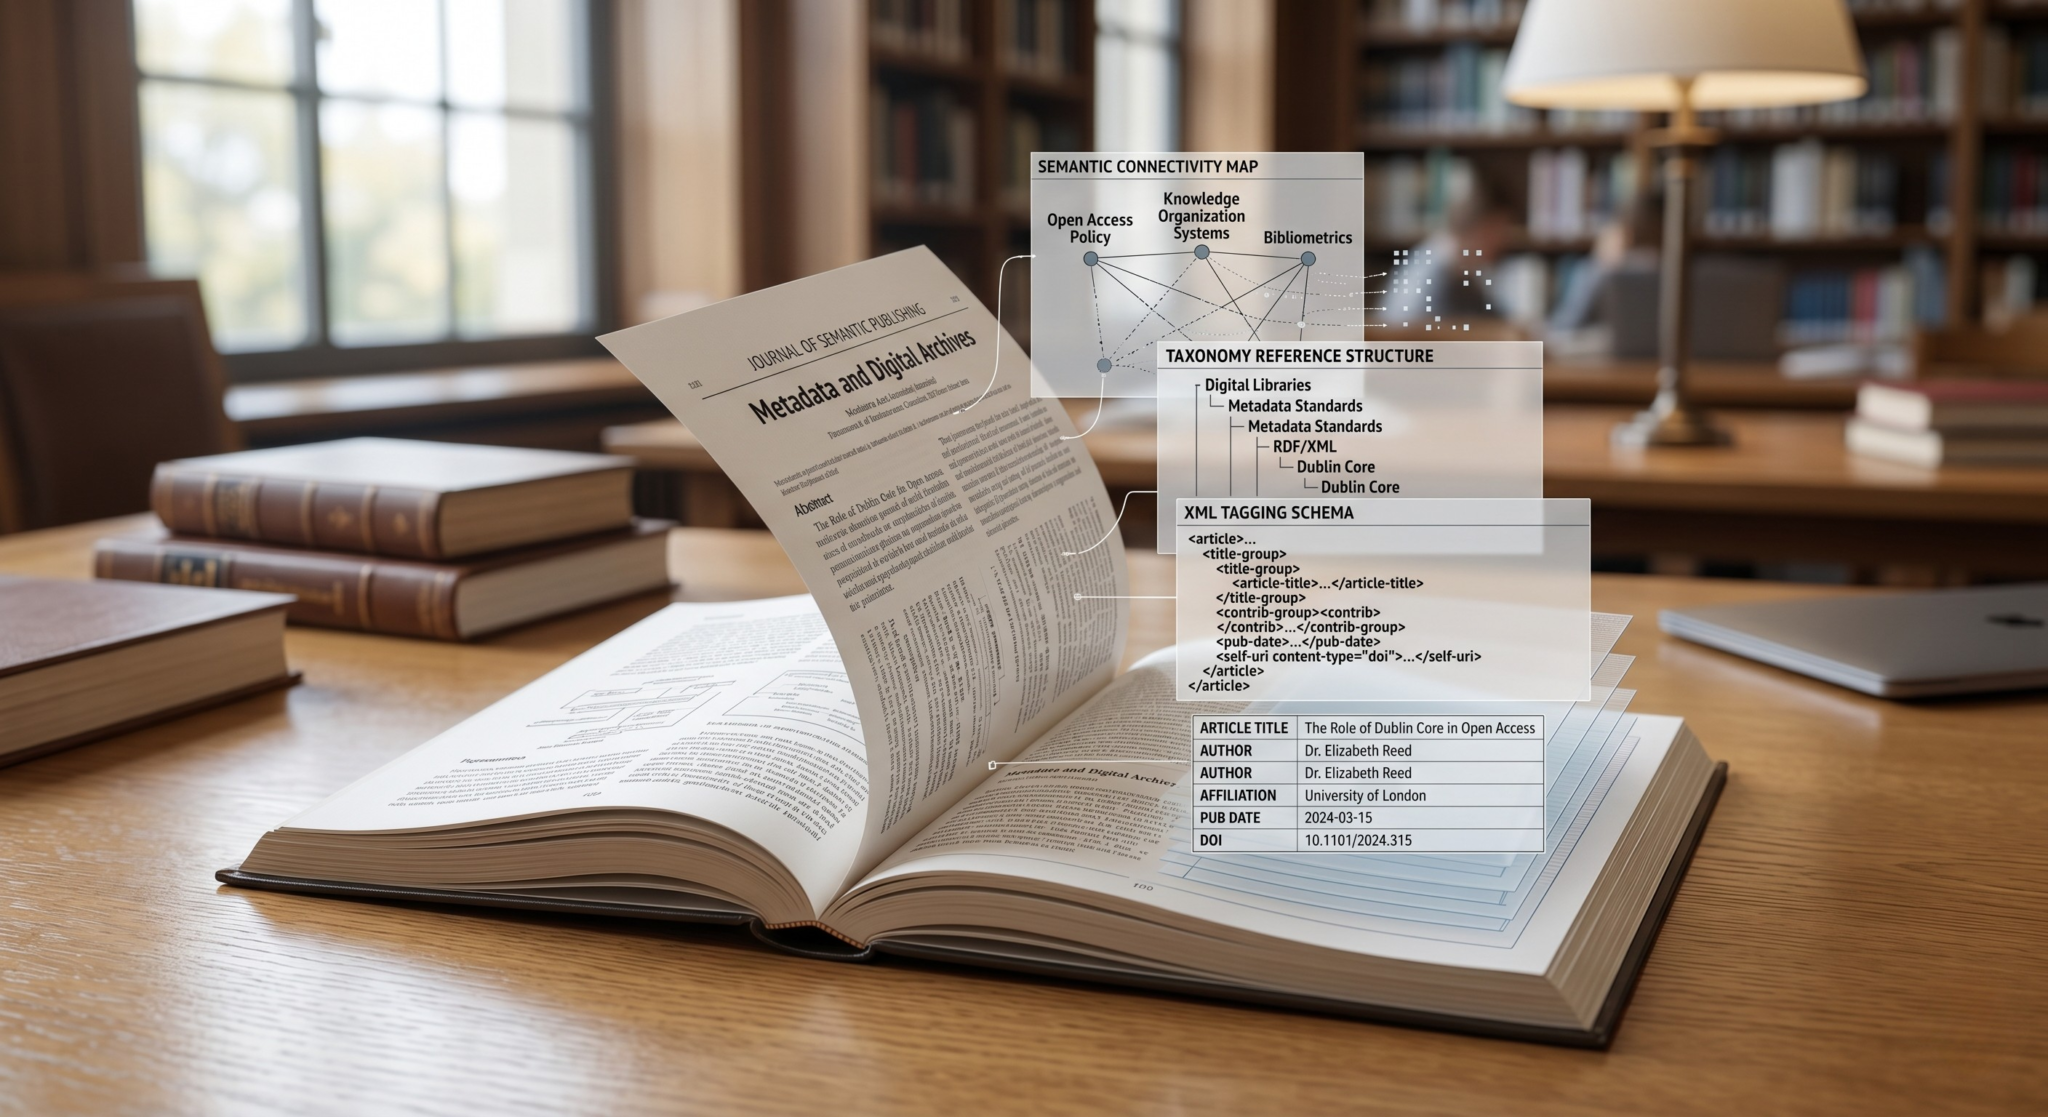
Publishing metadata is structured descriptive, administrative, and technical information about a content object that enables its discovery, access, rights management, and distribution. Poor metadata does not just make content harder to find it actively suppresses it in platform algorithms, breaks automated ingestion pipelines, and creates revenue leakage at the retail level.
Metadata exists at three functional layers, each serving a different operational purpose.
Descriptive metadata title, author, abstract, subject classifications, and keywords is what readers and discovery systems use to locate content. Errors here affect search ranking, subject category placement, and index inclusion. A journal article missing or incorrectly coded subject headings in Scopus or Web of Science may be formally published but effectively invisible to the researchers it is intended to reach.
Administrative metadata rights information, licensing terms, access restrictions, embargo periods, and publication dates governs how content can be used and accessed. ONIX 3.0 carries this data to retail platforms and library systems; errors result in incorrect access conditions, pricing display failures, or rights violations in institutional licensing agreements.
Technical metadata file format specifications, encoding standards, resolution, and structural markup is what production systems and platforms use to process content correctly. Invalid technical metadata is one of the leading causes of rejected submissions to aggregators and eBook retailers.
What "Good Metadata" Actually Looks Like in Practice
Good metadata is complete, consistent, and schema-compliant at every distribution point. For a journal article, this means: a registered DOI with CrossRef-compliant metadata, JATS-tagged abstract and keywords, correct ISSN attribution, article-level licensing terms (typically CC-BY or equivalent), and a complete author affiliation record. For a trade eBook, it means: a fully populated ONIX 3.0 feed with correct BISAC subject codes, contributor roles, territorial rights, pricing by currency, and a properly formed ISBN. The metadata standard is not the finish line consistent, validated delivery of that standard to every platform and aggregator in your distribution chain is.
How Digital Conversion Services Tie Platforms, XML, and Metadata Together
Digital conversion services are the production layer that transforms manuscript-stage content into validated, platform-ready output across multiple formats. The best digital conversion services in the US operate as strategic partners in this process not format converters because they manage the XML source, enforce schema compliance, embed metadata, and produce publication-ready files that can be ingested directly by platforms and aggregators without additional remediation.
The conversion layer sits between composition and distribution. Its function is to take validated XML or to create that XML from word processor or typeset files and generate format-specific outputs: PDF for print and archiving, EPUB3 for retail and library platforms, HTML for web delivery, and structured data exports for aggregator ingestion. When this layer is functioning correctly, a single editorial correction flows through to every output format automatically. When it is not, each format becomes a separate production silo requiring independent quality control.
The distinction between basic file conversion and publication-ready digital conversion is significant. Basic conversion produces syntactically valid output. Publication-ready conversion produces output that is schema-validated, accessibility-compliant, platform-tested, and metadata-complete output that passes aggregator ingestion checks, renders correctly across reading devices, and meets WCAG 2.1 accessibility requirements without post-conversion remediation.
Publishers working with Wordium have found that structuring digital conversion around an XML-first source rather than converting finalized PDFs or InDesign files reduces format-specific correction rounds by eliminating the structural inconsistencies that format-last production introduces. The XML becomes the authoritative source, and platform-specific outputs are generated from it, not alongside it.
Building a Future-Proof Publishing Stack Platform + Workflow + Metadata Aligned
A future-proof publishing stack is one in which platform selection, XML workflow design, and metadata management are architecturally aligned so that changes in any one layer (a new distribution partner, a schema update, a new accessibility requirement) can be absorbed without restructuring the entire production pipeline. |
The three-layer stack can be understood as follows: the content layer (XML source, editorial workflow, composition) feeds the distribution layer (platform ingestion, format conversion, metadata delivery), which enables the discovery layer (aggregator indexing, retail visibility, institutional access). When these three layers are designed independently as they often are in legacy publishing environments every change requires cross-layer remediation. When they are designed as an integrated system, changes are absorbed efficiently.
The Accessibility Layer: WCAG, ADA, and EPUB Accessibility as Non-Negotiables
Accessibility is no longer a downstream consideration. WCAG 2.1 compliance, ADA requirements in the US market, and EPUB Accessibility 1.1 standards now constitute baseline requirements for institutional library purchasing decisions, federal accessibility mandates, and an increasing number of publisher agreements with educational institutions. Publishers who retrofit accessibility at the end of the production cycle incur substantially higher remediation costs than those who design it into their XML workflows from the outset because accessibility in an XML-first environment is largely a tagging and structural decision made during composition, not an expensive post-production remediation exercise.
AI-Assisted QA and Automation in Modern Conversion Pipelines
The integration of AI-assisted quality checks into XML and conversion pipelines represents the current frontier of production efficiency for high-volume publishers. Automated validation against JATS or BITS schema, AI-driven metadata completeness checks, and programmatic accessibility audits are now operational capabilities not future possibilities. Teams that have transitioned to automation-driven production environments, including those working within Wordium’s’s end-to-end pipeline, report that the primary human review effort shifts from error detection to editorial judgment, the work that genuinely requires expert attention rather than mechanical verification.
Frequently Asked Questions
What is an XML-first publishing workflow?
An XML-first publishing workflow is a production model in which XML is created at the earliest stage of the editorial process during copyediting or composition and used as the single canonical source from which all output formats (PDF, EPUB3, HTML, print) are generated. This contrasts with XML-last workflows, where XML is produced as a final export from formatted files. XML-first workflows improve consistency across formats, reduce per-format correction cycles, and enable automated multi-format output from a single validated source.
Which XML schema should STM journals use, JATS or BITS?
STM journal articles should use JATS (Journal Article Tag Suite), which is the standard required by PubMed Central, CrossRef, Scopus, and most major academic aggregators. BITS (Book Interchange Tag Suite) is the appropriate schema for academic books and monographs it is structurally compatible with JATS but extends it to support book-level structural elements such as chapters, front matter, and back matter.
How does metadata affect journal discoverability on aggregator platforms?
Aggregator platforms including PubMed, Scopus, Web of Science, and ProQuest index content based on structured metadata fields. Missing or incorrectly coded subject classifications, incomplete author affiliation records, or unregistered DOIs can result in articles being excluded from relevant search results, incorrectly categorized within subject areas, or absent from citation indexes entirely. Metadata errors are frequently invisible to the editorial team but have a direct and measurable impact on article reach and citation rates.
What should I look for in the best digital conversion services in the US?
The best digital conversion services in the US go beyond file format transformation to deliver schema-validated, accessibility-compliant, metadata-complete output that passes platform ingestion requirements without remediation. Key indicators include: XML-first production capability, support for JATS, BITS, and ONIX standards, EPUB3 output that meets EPUB Accessibility 1.1 requirements, multi-format generation from a single XML source, and demonstrated experience with STM, academic, or K–12 publisher workflows.
How do I convert a manuscript to EPUB3 without losing formatting?
Reliable manuscript-to-EPUB3 conversion requires a structured XML intermediary not direct conversion from Word or PDF. The process involves: creating or validating a JATS or BITS XML source, applying semantic tagging for headings, figures, tables, footnotes, and equations, and then generating EPUB3 from that validated XML source. Direct conversion from unstructured formats produces EPUB files with inconsistent rendering across devices and frequent accessibility failures.
What is the difference between ONIX and Dublin Core metadata?
ONIX (Online Information eXchange) is a detailed commercial metadata standard used to communicate bibliographic, pricing, rights, and availability information between publishers, distributors, and retail platforms. It is the standard required by Amazon, Apple Books, Kobo, and most library platform providers. Dublin Core is a simpler, more general metadata standard used primarily for web resource description and archival purposes. Dublin Core has fifteen core elements and is used in open access repositories and library catalog systems; ONIX 3.0 has hundreds of codelist elements designed to support complex commercial publishing data requirements.
Can one XML source file produce PDF, HTML, and EPUB outputs?
Yes and for high-volume publishers, this is the primary operational argument for XML-first workflows. A single validated XML source file, properly structured against JATS or BITS schema, can serve as the input for automated transformation pipelines that generate print-ready PDF, web-delivery HTML, and EPUB3 simultaneously. Any content correction made to the XML source propagates to all output formats, eliminating version drift and reducing per-format quality assurance effort significantly.